
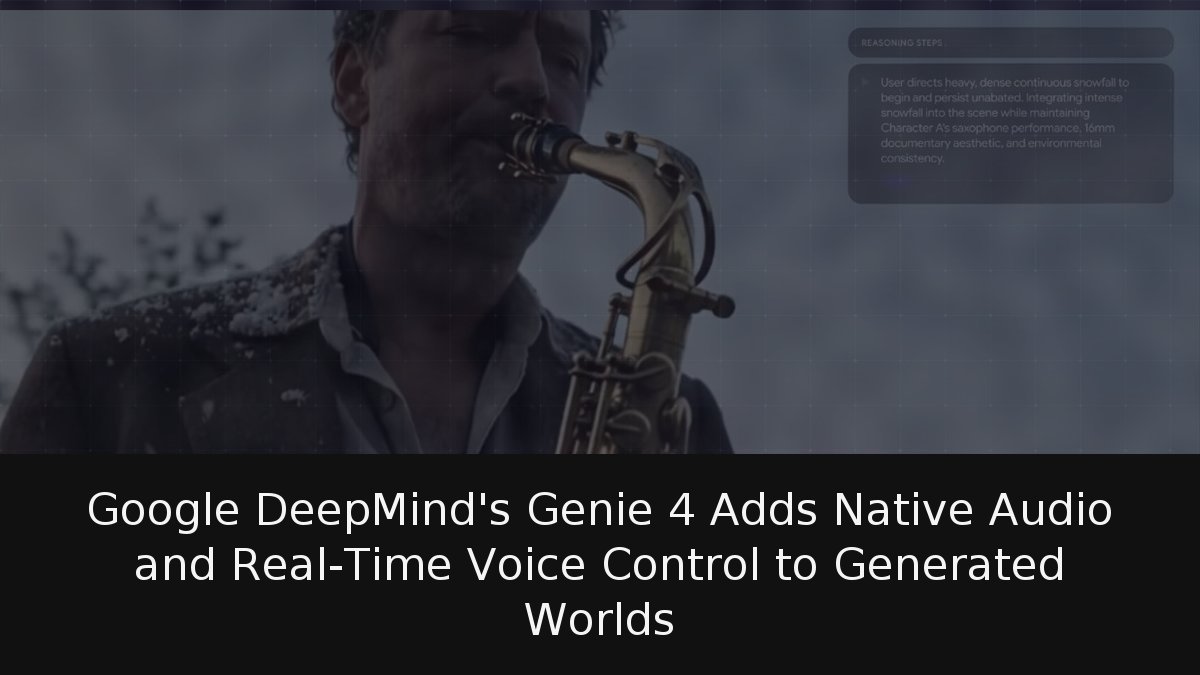
Google DeepMind has pulled back the curtain on Genie 4, the latest iteration of its world-simulation model, and the headline feature is sound. Unlike conventional video generators that output a fixed clip, Genie 4 builds an environment that reacts to your actions in real time, much like a video game nobody had to program. The model can now produce music, ambient noise and character dialogue natively, and users can reshape the world mid-session simply by describing what they want.
- Native audio generation: Genie 4 is the first Google model of its kind to synthesize sound, including dialogue from characters that converse and react.
- Real-time natural-language steering: Users can add characters, move the camera or change the weather while the world is running.
- Limited rollout: The model is in preview with trusted testers and will reach Google AI Ultra subscribers and select developers soon.
The announcement, dated October 27 and signed by Raia Hadsell, Diego Rivas and Hang Qi, was detailed on DeepMind’s blog and model page. A world model, the team stresses, is not a video generator: it does not produce a closed sequence but an environment that responds to what you do at every moment.
What Genie 4 can do
According to DeepMind, users can describe landscapes and events, reposition the camera, introduce characters or alter the climate while the simulation is live. The model simulates aerodynamics and collisions, along with natural human movement that can also be directed in real time.
The audio layer is the major novelty: music, environmental sound and dialogue, with characters that hold conversations and react to events. To achieve realism, Genie 4 leans on two other Google models. Gemini Omni anchors the appearance and behavior of the real world, while Gemini 3.8 Flash acts as an agent that observes, breaks objectives into steps and verifies them.
DeepMind also demonstrated a robotics use case: combined with Gemini 4 Argon and Gemini Robotics, the model simulated Apptronik’s humanoid Apollo playing checkers.
The limits DeepMind is willing to admit
The company lists the shortcomings without sugar-coating them. The model sustains only a few minutes of continuous interaction rather than long sessions. TechCrunch reports that it keeps a scene coherent for up to two minutes, double that of Genie 3, a figure Google does not publish on its own pages. Visual details and object permanence can drift over time, real locations are not reproduced accurately, legible text appears almost exclusively if it was in the initial description, and real-time audio precision remains an active research problem.
Google has not disclosed resolution, frame rate or pricing. Everything the model generates will carry the invisible SynthID watermark, applied to both video and audio.
Where the model is headed
DeepMind cites creative direction and previsualization, historical recreations built from archival photos, concept design and enterprise simulations, with testers drawn from creative, journalistic, educational, gaming and engineering fields. Diego Rivas, an engineer at DeepMind, acknowledged to TechCrunch that these are still early days.
These are still the first days.
The launch lands in a crowded race. Runway has its second world model, AMD has acquired World Labs and Amazon is reportedly in talks with Decart, according to press reports. Google had already signaled its direction with Playground, its platform for building games from a description, and Genie 4 is the piece that generates the world itself. It is the logical evolution of multimodal models that already combine image, audio and video.
The most consequential aspect of Genie 4 is not the two-minute world but the wiring into Google’s language and robotics models. That is where near-term value lies: training and testing robots or agents in simulated environments nobody had to build by hand. As a consumer product, it remains an expensive demo, headed for Google’s priciest plan and a handful of developers in the coming weeks, with no price and no confirmation of availability in every market.